https://leafw-blog-pic.oss-cn-hangzhou.aliyuncs.com/avatar.jpg

Putting a CPU Inside Qwen: How Qwenputer Runs RISC-V Within the Model
https://leafw-blog-pic.oss-cn-hangzhou.aliyuncs.com/qwenputer-cover.png

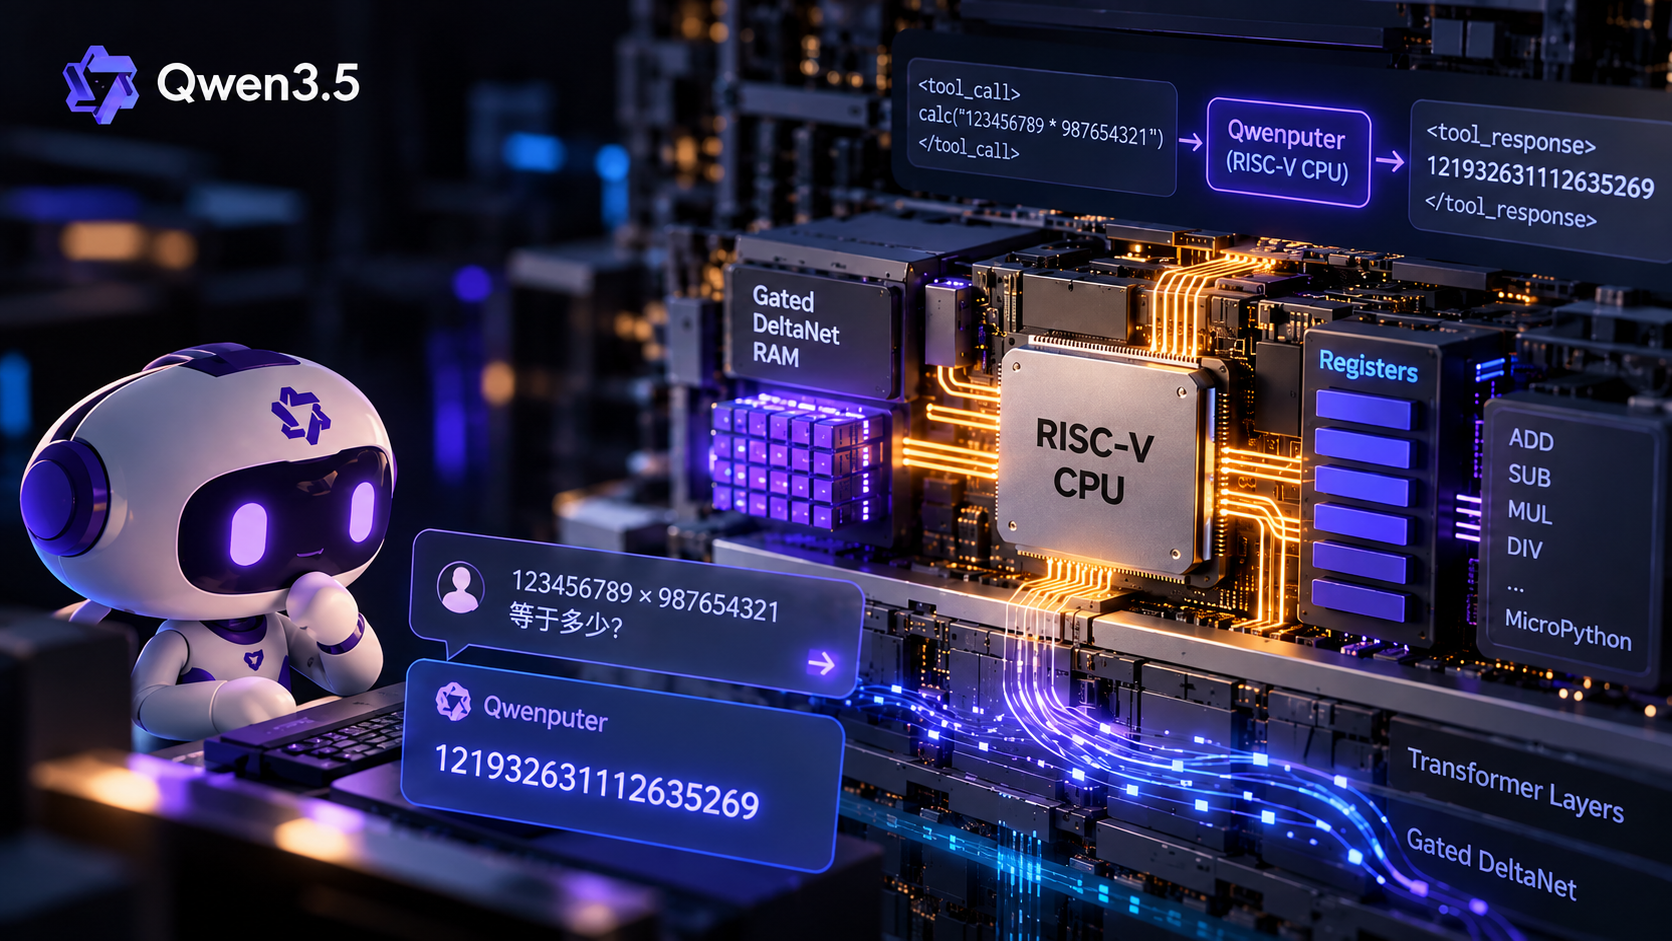
On October 22, a researcher named Divyansh Agrawal published a fascinating technical write-up: Qwenputer: a fully functioning, deterministic RISC-V CPU inside Qwen3.5.

The author did something that sounds almost impossible: embedded a complete 32-bit RISC-V CPU inside the neural network of Qwen3.5-4B.

This CPU can execute integer arithmetic and C programs, and its underlying compute core can even run MicroPython. It doesn’t call an external Python interpreter or any calculation tool; the CPU instructions themselves are executed by the model’s forward pass.
Anthropic Is Going Public: What the S-1 Reveals About Its Books

https://leafw-blog-pic.oss-cn-hangzhou.aliyuncs.com/anthropic-s1-cover.png

On October 26, Anthropic filed its S-1 registration statement with the U.S. Securities and Exchange Commission (SEC). The S-1 is the registration document a U.S. company must file before its initial public offering, covering its business, financials, risks, and ownership structure. This filing lays out Anthropic’s revenue, losses, compute spending, and equity arrangements, and Claude Code gets a dedicated spot in it as well.

Anthropic: Don't Rush to Split Out Sub-Agents

https://leafw-blog-pic.oss-cn-hangzhou.aliyuncs.com/fold-subagents-single-loop-cover.png

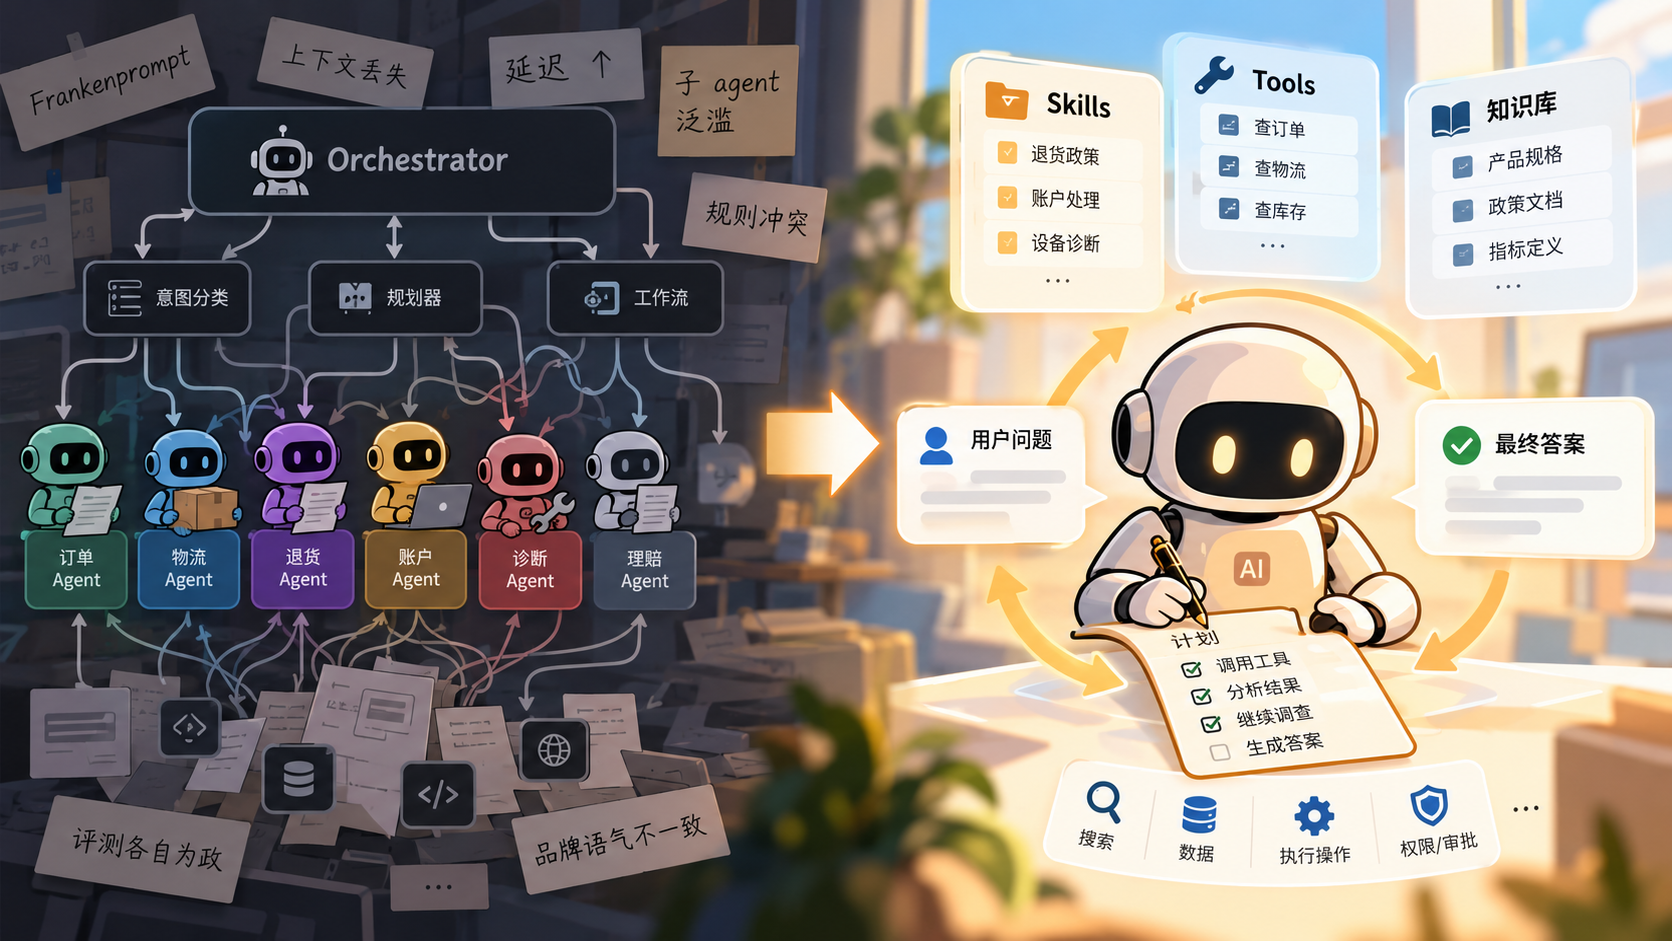
A few days ago I wrote a breakdown of a paper on parallel sub-agents. The takeaway: turning on concurrency generally hurt scores on short tasks, while on long tasks the results were mixed. On October 22, Anthropic published an article on the Claude website, “Building agents: When to fold subagents into your main agent loop”, written by Anthropic’s Diane Sarkis. It’s about when you should fold sub-agents back into the main loop, that is, merge a sub-agent’s prompt and capabilities into the main agent so they become its skills and tools.

Do More Sub-Agents Make Better Code?

https://leafw-blog-pic.oss-cn-hangzhou.aliyuncs.com/parallel-subagents-main-agent-cover.png

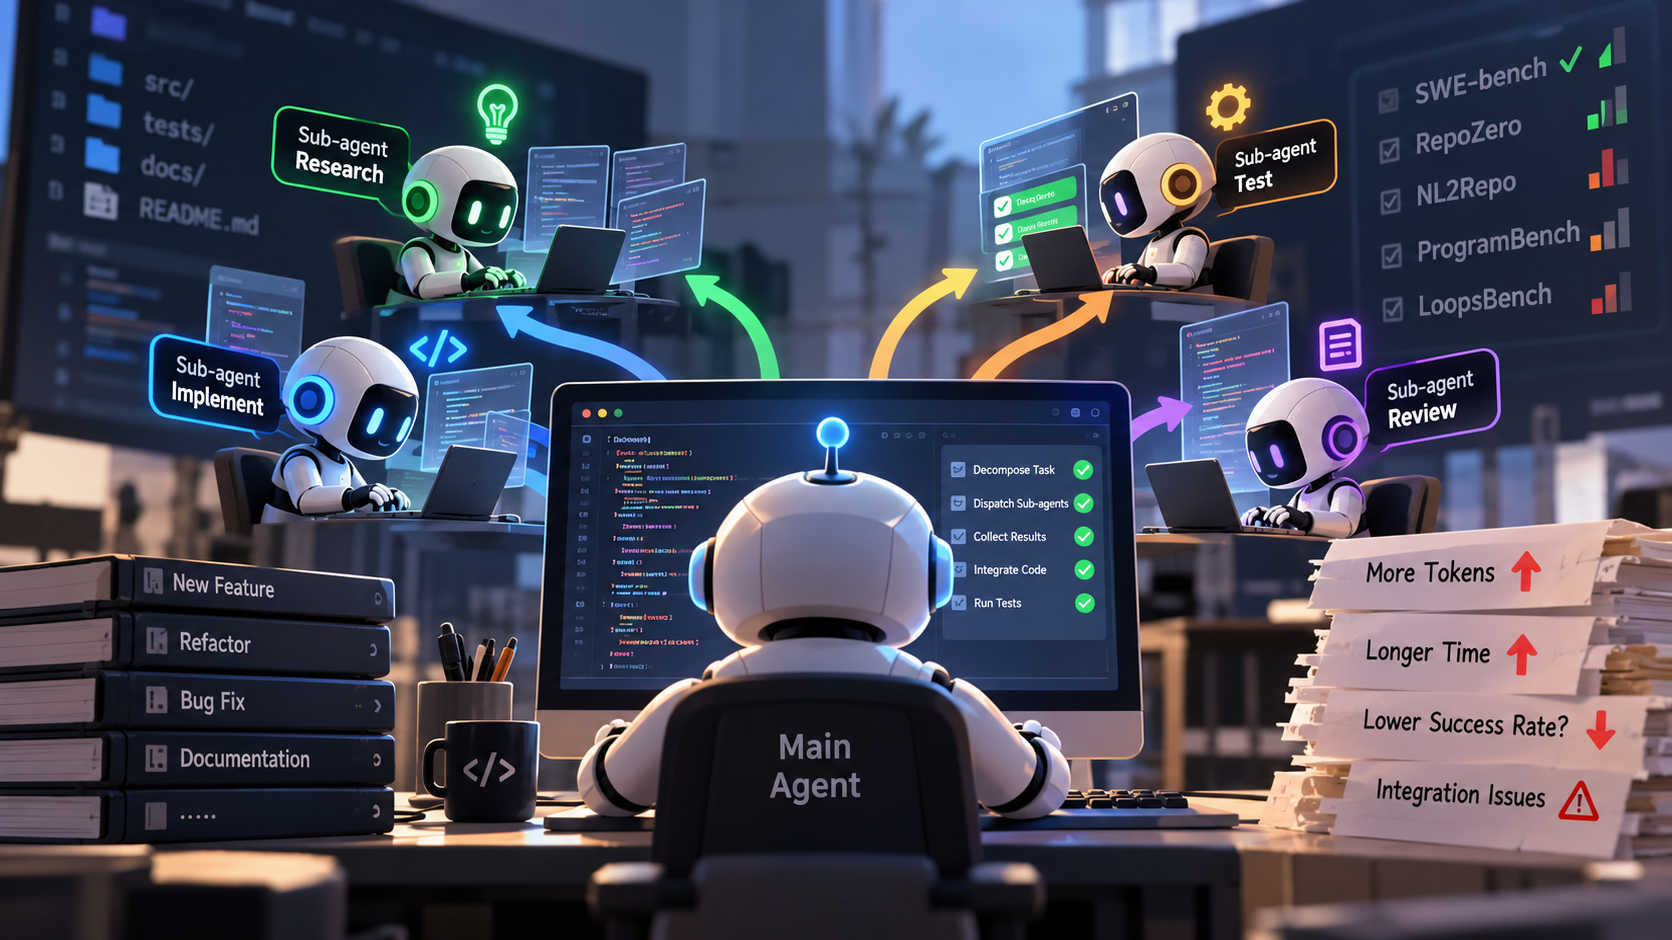
Many agent products now let a main agent spin up a batch of sub-agents to work in parallel. But how well does multi-agent collaboration actually work, and is it always better than a single agent? Few people bother to compare.

I recently read a paper that does exactly that: When Sub-Agents Work in Parallel: The Promises and Pitfalls of Dynamic Concurrency in Long-Horizon Coding Tasks, https://arxiv.org/abs/2610.10263 . The work comes from Nanjing University, Central University of Finance and Economics, and the University of Illinois Urbana-Champaign, by Han Li, HanHaoNing Li, Ziqian Jiang, and Yiling Lou. They turned the built-in sub-agent concurrency of three coding agents, Codex, Claude Code, and Kimi Code, on and off, and ran each setting on 354 tasks: 2,124 runs in total, with 11.2 billion tokens logged, which comes to $20,780.02 at standard API prices.

How the Claude Code Team Does Code Review When Agents Write the Code

https://leafw-blog-pic.oss-cn-hangzhou.aliyuncs.com/claude-code-review-postgres19-cover.png

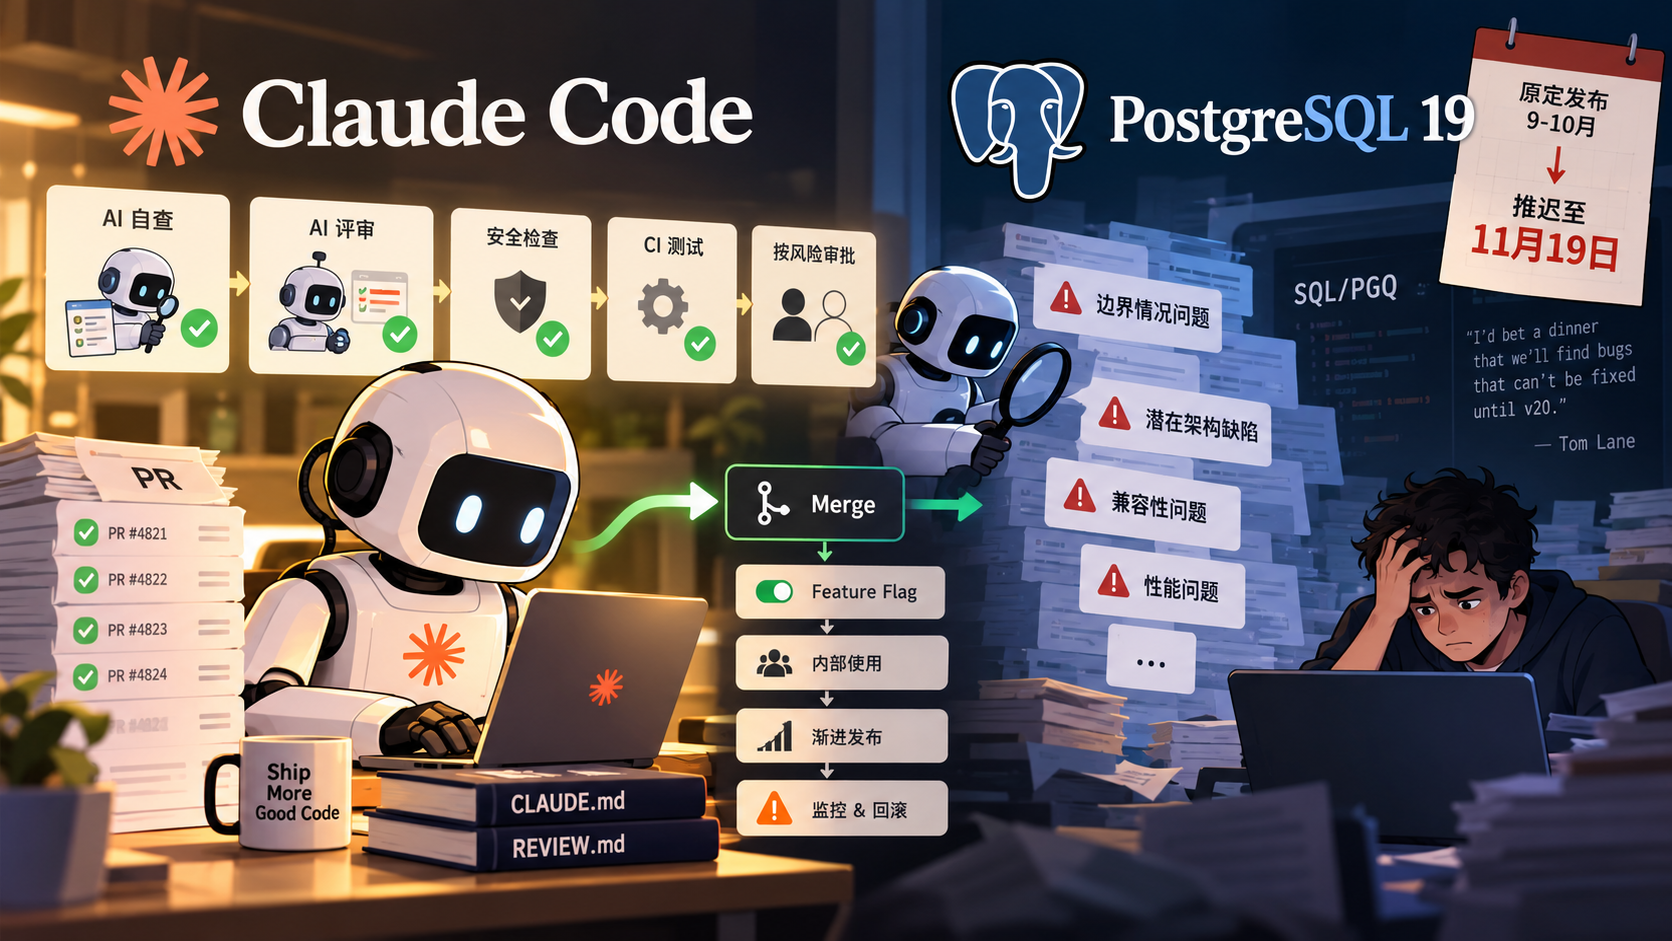
With coding agents like Claude Code and Codex, PRs get opened far faster than before. Agents keep working overnight, and you may wake up to several PRs waiting to be merged. The code gets written faster, but the people reviewing it are still the same few.

This week I read two pieces that are worth looking at together. One is How the Claude Code team does code review, published by the Claude Code team on the claude.dev blog and signed by Addy Osmani, Morgan Westlee Lunt, and Qing Wang. It describes how they do code review now that agents write most of the code. The other is an October 16 report from The Register: the release of PostgreSQL 19 has been delayed, and one of the reasons has to do with AI-assisted code review.